ElevenLabs is a genuinely good product. It’s also $22/month for the Starter tier, $99/month for Creator, and every voice you generate sends audio data to their cloud. For most people using it casually, those are reasonable trade-offs for the quality and convenience.
Voicebox is a bet that a growing segment of users — developers, privacy-conscious creators, teams that can’t send audio data to external servers — want something different. Local-first. Free. Open source. No subscription. Your voice data never leaves your machine.
Built by Jamie Pine — the same developer behind Spacedrive — Voicebox is a local-first voice cloning studio that leverages Alibaba’s Qwen3-TTS model to achieve near-perfect voice cloning from just a few seconds of audio. It went from zero to 22,884 GitHub stars in roughly three months. That’s not a curiosity. That’s a signal worth paying attention to.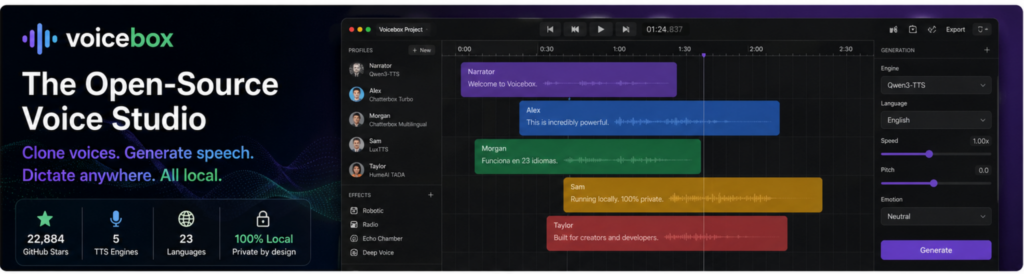
Voicebox isn’t a thin wrapper around someone else’s API. It’s a local-first voice cloning studio — a free and open-source alternative to ElevenLabs. Clone voices from a few seconds of audio, generate speech in 23 languages across 5 TTS engines, apply post-processing effects, and compose multi-voice projects with a timeline editor.
The application combines the intuitive workflow of a Digital Audio Workstation (DAW) with state-of-the-art machine learning, allowing you to create voice profiles, generate speech, and compose multi-voice projects without writing a single line of code. Yet, it’s simultaneously API-first, meaning every function exposed in the graphical interface is also available through a clean REST API for programmatic integration.
Prerequisites: Bun, Rust, Python 3.11+, Tauri Prerequisites, and Xcode on macOS. The project ships with a pre-wired .mcp.json at the root — running Claude Code inside this checkout picks up the Voicebox MCP tools automatically once the dev app is running.
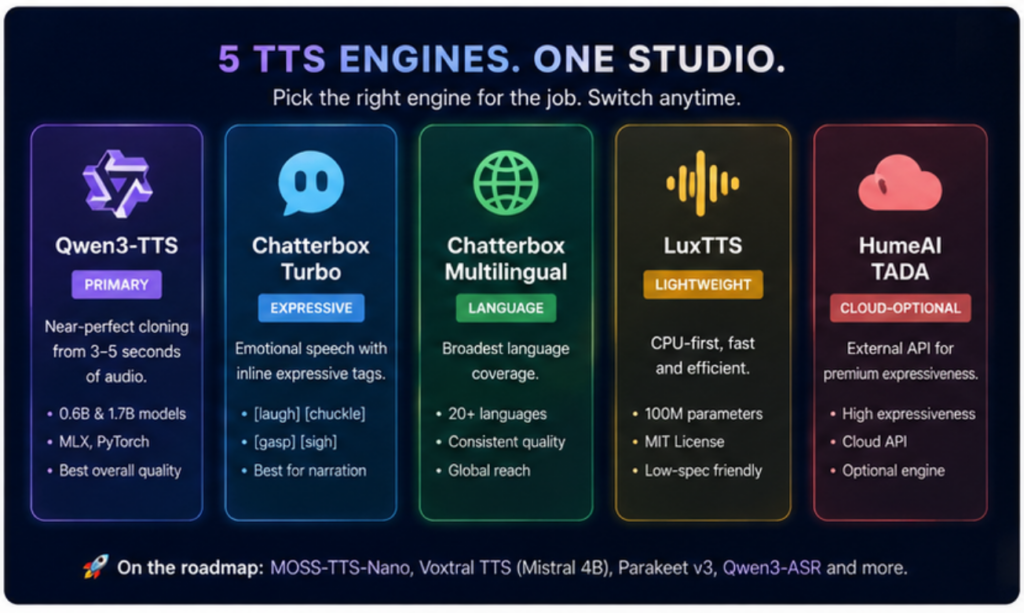 The 5 TTS Engines — Pick the Right One for Your Use Case
This is the feature that sets Voicebox apart from single-model tools. Five TTS engines with different strengths, switchable per-generation. You’re not locked into one model’s quirks — switch based on what the task needs.
Primary / Recommended
Alibaba’s breakthrough model that achieves near-perfect voice cloning from just a few seconds of audio. Requires only 3–5 seconds of clear audio for basic cloning. Runs via MLX on Apple Silicon, PyTorch on everything else. Available in 0.6B and 1.7B parameter sizes.
Expressive / Emotional
Supports expressive tags that the model synthesizes inline with speech: [laugh] [chuckle] [gasp] [cough] [sigh] [groan] [sniff] [shush] [clear throat]. Best for content where emotional range matters — podcast voiceovers, character dialogue, narration.
Language Coverage
Broadest language coverage — Arabic, Danish, Finnish, Greek, Hebrew, Hindi, Malay, Norwegian, Polish, Swahili, Swedish, Turkish and more. Best for multilingual content where quality consistency across languages matters more than emotional range.
Lightweight / CPU
CPU-first, 100M parameter model, MIT license. Best for lower-spec machines or situations where you need fast generation without GPU acceleration. Covers several European languages.
Cloud-optional
The one engine in the lineup that uses an external API. Included for quality comparison and specific use cases where Hume’s expressiveness model is the right fit. Optional — the other four run fully locally.
MOSS-TTS-Nano (0.1B params, Apache 2.0, 4-core CPU realtime, 48 kHz stereo, streaming, 20 languages) and Voxtral TTS (Mistral 4B) are the next planned additions. Parakeet v3 and Qwen3-ASR are also in the pipeline.
 The April 24 Update — Why Everyone’s Talking Now
The April 24 update is why the source article says “ElevenLabs is finished.” That’s overstated — but the update does push Voicebox out of “voice cloning tool” territory and into “daily workflow tool” territory, which is a meaningful category shift.
🎙️ System-Wide Dictation (Wispr Flow territory)
Hold a hotkey anywhere on your system, speak, release — on macOS the transcript pastes straight into the focused text field. It runs OpenAI Whisper for transcription on MLX (Apple Silicon) or PyTorch (CUDA/ROCm/DirectML/CPU) depending on your hardware.
Configurable chord bindings — hold-to-speak and tap-to-toggle chords, each rebindable in the in-app chord picker. Holding push-to-talk and tapping Space mid-hold upgrades into a toggle session without a gap in audio.
🤖 LLM Refinement — Clean Up Your Dictation Automatically
Optional cleanup of ums, stutters, and false starts before paste. A bundled Qwen3 LLM runs entirely locally — so your dictation gets cleaned up without sending text to any external server. Same LLM backs the personality rewrite feature.
💬 ChatGPT + Claude Voice Integration
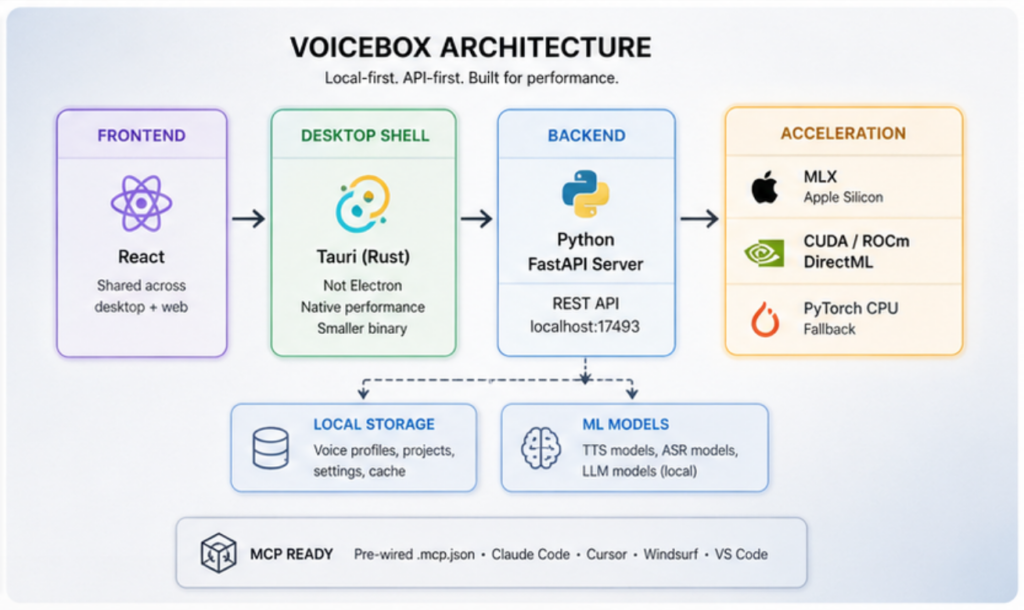
HTTP + stdio transports — install as a URL in Claude Code / Cursor / Windsurf / VS Code MCP, or point stdio-only clients at the bundled voicebox-mcp binary. This means you can voice-command Claude or ChatGPT directly from Voicebox — speak your prompt, have it transcribed and refined, then piped to the LLM.
🎭 Voice Personalities — Speak In Character
Attach a free-form personality to any voice profile — who this voice is, how they speak, what they care about. “Speak in character” routes your input text through the personality LLM to be rewritten in their voice before TTS. Useful for game dialogue, audiobooks, character voices, and branded voice assistants.
8 audio effects powered by Spotify’s pedalboard library. Apply after generation, preview in real time, build reusable presets. Ships with 4 built-in presets (Robotic, Radio, Echo Chamber, Deep Voice) and supports custom presets. Effects can be assigned per-profile as defaults.
Available effects: pitch shift, reverb, delay, chorus, compression, and filters. Each assignable per voice profile as a default.
Mac and Windows pre-built binaries available from the GitHub releases page or voicebox.sh. Linux builds are coming — currently blocked by GitHub runner disk space, but build-from-source instructions exist at voicebox.sh/linux-install.
Prerequisites: Bun, Rust, Python 3.11+, Tauri Prerequisites, and Xcode on macOS.
| Factor | Voicebox | ElevenLabs |
|---|---|---|
| Price | Free (open source) | $22–$99+/month |
| Data privacy | 100% local — nothing leaves your machine | Cloud-based — audio sent to ElevenLabs servers |
| Voice cloning sample needed | 3–5 seconds | Varies by tier (~1 min for Pro) |
| TTS engines | 5 (switchable per generation) | Proprietary models only |
| API access | localhost REST API — free, unlimited | API credits — metered and paid |
| Dictation | Built-in (Whisper, local) | Not available |
| Audio effects / post-processing | 8 effects (Spotify pedalboard) | Limited |
| Multi-voice timeline editor | Yes — DAW-style | Limited / Projects feature |
| Output quality ceiling | Very high (Qwen3-TTS) | Best-in-class (for now) |
| Stability / production-ready | Active development — some rough edges | Polished, production-ready |
just setup && just dev from source.Already running Voicebox? Drop your setup and impressions in the comments — especially curious how Qwen3-TTS quality compares to ElevenLabs on real-world audio.


